Custom API development is not just a matter of exposing a few endpoints or connecting two systems. A reliable integration is a contract between teams and services: it defines what data means, who may act on it, how failures are represented, and what happens when messages arrive late or more than once. If those decisions remain implicit, a workflow that succeeds in a demo can create duplicate orders, stale CRM records, leaked customer data, or manual cleanup in production.
This playbook gives product, engineering, and operations teams a practical way to plan an API or integration from the business workflow outward. It covers contract design, authentication, data mapping, idempotent writes, retries, webhooks, testing, deployment, and long-term ownership. Examples use a fictional B2B order workflow; adapt the names and controls to the actual providers, data, and contractual requirements. Do not assume a provider offers a feature unless its current documentation confirms it.
On this page
- Start With the Workflow and Integration Contract
- Design Resources, Authentication, and Errors
- Map Data and Protect Compatibility
- Make Writes Safe: Timeouts, Retries, and Idempotency
- Connect Systems With Webhooks and Async Jobs
- Test the Contract and the Failure Paths
- Operate, Monitor, and Evolve Integrations
- Frequently Asked Questions
- Conclusion
- Sources
Start With the Workflow and Integration Contract
Trace one business outcome end to end
Begin with an outcome a user can recognize, such as “an approved order appears in the fulfillment system and the sales team can see its status.” Map each step from the event that starts the work to the state that proves it finished. Name the system that owns each fact. The CRM may own account relationships, the billing platform may own payment status, and the order service may own fulfillment state. A field appearing in two systems does not make both systems authoritative.
For a fictional distributor, an account manager approves a quote, the commerce service creates an order, the inventory provider reserves stock, and the CRM receives an order reference. Write down what must be true at every handoff: the account is matched, the quote is still valid, the requested products have stable identifiers, and the final order can be traced back to the originating quote. This exposes the real integration requirements before anyone selects endpoints or starts copying fields.
Create a small workflow table with the trigger, owner, input, output, failure response, and human owner for each step. For example, “quote approved” may be the trigger; the quote service owns the approval; the order API receives a quote ID and requested items; and an operations queue owns cases that cannot be matched automatically. If no one owns a failure path, the system will likely turn it into an unmonitored retry loop or a support ticket without enough context.
Decide whether an API is the right boundary
An API is useful when another application or team needs a stable, controlled way to request or read data. It is not automatically the best answer for every data transfer. A scheduled export can be simpler for a low-frequency batch process; a message broker can fit durable asynchronous work; a webhook can notify a consumer about a change. Choose based on latency, volume, ownership, recovery needs, and the consumer’s ability to process events.
For each interaction, state whether the caller needs an immediate answer. A request to validate a tax ID may need a synchronous result. A large nightly reconciliation can run asynchronously and return a job ID. A payment or inventory status change can be delivered as an event. These distinctions matter: synchronous calls tie the user experience to the availability of every dependency, while asynchronous flows require clear status, retry, and reconciliation behavior.
Write down the contract before implementation
A contract describes the public behavior a consumer can rely on, not the internal classes or database tables. Define the resource names, supported methods, required fields, optional fields, validation rules, authentication, error responses, pagination, rate limits, and compatibility expectations. OpenAPI is a language-neutral format for describing HTTP interfaces, which lets teams review the contract and use compatible tooling for documentation and client generation.
For a first version, put the contract in a version-controlled OpenAPI document and review it with both the API owner and a representative consumer. Ask the consumer to walk through a normal request, a validation failure, an authorization failure, a timeout, and a retry. If the only explanation is “the consumer can inspect our code,” the contract is not yet a dependable boundary.
Keep a concrete example beside the schema. A request to create an order might contain a client reference, an account identifier, line items, currency, and a requested delivery date. The response should return the service’s order ID, accepted state, creation time, and a link or route for checking progress. Clarify whether unknown fields are ignored or rejected, how missing values differ from explicit nulls, and whether an omitted collection means “leave unchanged” or “clear it.” Those details often cause integration defects even when both services use JSON.
Design Resources, Authentication, and Errors
Model resources and actions clearly
Use names that describe business resources and keep the method’s behavior predictable. A path such as /v1/orders/ord_123 refers to one order; GET reads it, while a documented update method changes supported fields. A command-like operation may still be appropriate when the business action is not naturally a resource update, but name it consistently and explain its side effects. Do not expose database table names as the public model unless that is genuinely the domain language consumers need.
Design each operation around a defined authorization scope. A user who can view an order may not be allowed to refund it, export its full customer details, or change the account that owns it. Enforce authorization on the server for every operation, including background tasks and administrative endpoints; hiding a button in the client is not a security control. For a multi-tenant service, derive tenant context from the authenticated identity and verify it against the requested resource.
Authentication establishes who or what is calling; authorization decides what that identity may do. For a server-to-server integration, use the provider’s supported credential flow and give each integration only the scopes it needs. Keep secrets in the deployment platform’s secret store or an equivalent protected system, not in source code, browser JavaScript, logs, screenshots, or a shared spreadsheet. Rotate or revoke credentials when an owner changes or exposure is suspected, and document how to do it without interrupting unrelated integrations.
Make errors actionable and safe
Return a consistent error shape with a stable machine-readable code, a short human explanation, and a request or trace identifier. A validation response should identify which field failed and what kind of value is expected without echoing sensitive input. An authorization failure should not reveal whether another customer’s private record exists. A dependency outage should be distinguishable from a permanent business rejection so the caller knows whether retrying could help.
Use HTTP status codes according to their documented meaning and avoid returning success for a request the service has not accepted. If processing will finish later, return an accepted response and a job or resource URL that the consumer can poll. If a dependency times out after the API has sent a write, the client may not know whether the operation completed. Design an idempotency strategy before that uncertainty reaches production.
Include request IDs in logs and support instructions. When a customer reports a failure, support should be able to locate the relevant attempt without asking for a full access token, payment data, or a raw customer export. Keep errors helpful to the operator while limiting information that would assist an attacker. Avoid exposing stack traces, SQL, internal hostnames, or secret-bearing URLs to API consumers.
Define pagination, filtering, and limits
Collection endpoints need bounded pagination so one request cannot retrieve an unmanageable amount of data. Document the page size, continuation token or cursor, ordering guarantees, and what happens if records change during a multi-page export. Prefer a stable cursor for large or frequently updated collections. If the consumer needs only a subset, define supported filters and fields rather than encouraging it to download everything.
Rate limits should protect the service and be predictable to consumers. State what is counted, whether limits vary by credential or tenant, and how a caller should respond to a limit error. Return retry guidance when available, and make the limit visible in account or API documentation. Do not tell consumers to retry continuously; backoff should include a delay and a cap, and non-retryable errors should stop the loop.
Map Data and Protect Compatibility
Treat data mapping as a business decision
Before mapping fields, identify the business meaning, owner, format, and update rule for each important value. “Customer” may mean a company in one system, a billing account in another, and an individual contact in a third. Mapping those records by display name is unsafe when names can change or collide. Prefer stable provider IDs and keep the source system and last synchronization time where reconciliation requires them.
Make transformations explicit. A source value of pending_review should not silently become approved because the destination has no matching state. Define a translation table, preserve an unknown value for review, or reject the record with a clear error. Normalize units and time zones deliberately: “$100” without a currency, or a local date without a time zone, is not a complete financial or scheduling value.
For each field, choose a conflict rule: source wins, destination wins, latest valid update wins, or human review. “Last write wins” is not a neutral default if the clocks differ or an older event arrives late. Record enough provenance to explain why a value changed. If a field is derived, identify its inputs and the system allowed to recalculate it.
Version contracts without surprising consumers
Treat the API as a contract. Prefer additive, backward-compatible changes: adding an optional response field is usually easier to adopt than renaming or removing an existing one. Before a breaking change, identify affected consumers, publish a migration path, support overlapping versions when feasible, and define an end-of-support date. Microsoft’s API design guidance notes that breaking changes can disrupt dependent clients and that multiple supported versions add maintenance and operational cost; version deliberately rather than versioning every small implementation change.
Document what compatibility means for your service. Can a client ignore unknown response fields? Are enum values open-ended? Can a field become nullable? Does a change to validation reject requests that previously passed? Consumers often generate code from schemas, so a change that looks harmless in a server implementation may still break a client build. Review contract diffs and test representative consumers before release.
If you need a breaking major version, keep the old route or schema available long enough for a managed migration, unless a security or legal requirement forces faster action. Provide examples of the old and new request, explain the behavior difference, and give consumers a way to test their migration. Monitor traffic by API version or client identifier so the owner can see who still depends on the older contract without logging secrets.
Keep duplicate records and drift visible
External integrations fail in ways that produce partial success. The API may create a contact while the CRM update times out. A webhook may arrive after a nightly import. A user may edit the same field in two systems. Plan reconciliation as part of the integration, not as a later cleanup project.
Store a stable mapping between the local object ID and the provider’s object ID. Use a unique constraint or equivalent control to avoid creating a second mapping for the same logical object. Track synchronization state, last successful attempt, last error category, and whether a human action is needed. Avoid keeping full provider payloads indefinitely when a small, redacted diagnostic record is enough.
Create an exception queue for records that cannot be safely matched or transformed. Each item should show the source object, destination, reason, current owner, and a supported action such as retry, correct mapping, or dismiss as duplicate. Provide a replay mechanism that reuses the original business intent while preventing a second side effect. If the data changes after the failed attempt, require the operator to review the changed fields rather than blindly replaying stale values.
Example: reconcile a partially completed order sync
Imagine the order API accepted an order but the CRM update failed. The integration should retain a compact mapping record that can answer which local order corresponds to which provider order, what step succeeded, and what remains. Keep the record focused on identifiers and state; do not copy a full customer payload into an operational table merely to make troubleshooting convenient. A record can look like this:
{
  "local_order_id": "ord_local_4821",
  "provider": "fulfillment",
  "provider_order_id": "ord_ext_99410",
  "sync_state": "crm_update_pending",
  "last_successful_step": "provider_order_created",
  "retry_after": "2026-10-18T02:15:00Z"
}
When a worker resumes, it should first load this mapping and fetch the provider order using its stable external ID. Then it can retry only the CRM step, without repeating order creation. If the lookup returns no order, the worker should compare the original request reference and operation history before deciding whether a create can be retried. If it finds two plausible matches, it should stop automated writes and route the record to an operator with both IDs and the reason for ambiguity. The expected outcome is one provider order, one CRM reference, and a visible audit trail that explains how the integration reached that state.
Make Writes Safe: Timeouts, Retries, and Idempotency
Set timeouts by operation
Every network request should have a finite timeout. An unlimited wait can tie up workers, consume connection pools, and make the whole service appear stuck. Choose a timeout based on the user-visible service objective, the provider’s documented behavior, and the workflow’s recovery options. Separate connection timeouts from response timeouts where the client library allows it, and record which phase failed.
For a synchronous screen action, a slow provider may require moving the work to a queue and returning a job status rather than holding the browser request open. For a batch import, a longer processing window can be acceptable if progress is visible and a retry resumes safely. Avoid copying one arbitrary timeout to every integration without understanding the effect on each workflow.
Retry only when the failure can recover
Retries help with temporary network failures, throttling, and selected server errors. They do not repair invalid data, missing permissions, or a request that violates a business rule. Classify errors into retryable and non-retryable groups, apply exponential backoff with jitter, and set a maximum attempt count or elapsed time. If the provider returns a retry-after value, honor it when appropriate. After the retry budget is exhausted, record the failure and route it to a visible recovery path.
Do not let every layer retry independently. A browser retry, API retry, queue retry, and provider SDK retry can multiply into a burst. Choose which component owns retries, define an overall deadline, and make the attempt count observable. During an outage, a circuit breaker or queue pause can prevent the integration from flooding a failing dependency; define what signal allows it to resume and how pending work is handled.
Use idempotency for operations with side effects
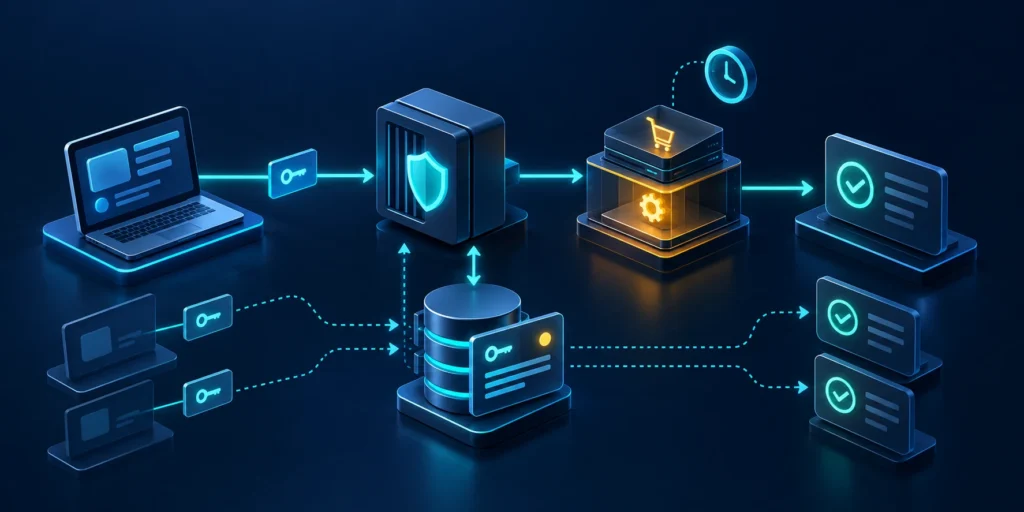
Idempotency means repeating the same logical request does not create the same side effect more than once. It is essential when a connection fails after a write may have reached the provider. The caller should create a unique key for the business action, store it with that action, and reuse it only when retrying that same request with unchanged parameters. Stripe’s API documentation describes this pattern for safely retrying certain create or update requests; provider-specific behavior and retention rules still need to be followed.
Example: a checkout service submits an order and times out before receiving the response. It must not generate a new idempotency key on every retry, or the provider may treat each attempt as a new order. A stable key derived from the internal order operation lets the receiving service recognize the retry. Do not place email addresses, access tokens, or other sensitive values in the key. Store the key securely and define how long the application retains its mapping.
#### Example: recover an uncertain order-creation response
Suppose the order service sends a create request and the connection closes before the response arrives. The operator cannot infer from the timeout alone whether the provider created the order. The safe runbook checks the provider by the stable client reference or replays the original request with the same idempotency key; it does not submit a new order with a fresh key. If the provider supports neither lookup nor idempotency, pause automatic retries and reconcile through the provider’s supported process before creating another order.
- Persist the internal order operation and its idempotency key before the outbound call.
- Send the same key on retries of the unchanged request.
- If the response is still unknown, query the provider using a stable external reference when supported.
- Mark the operation complete only after a persisted provider response or a confirmed reconciliation result.
A request might carry the key in a header like this; the exact header name and retention behavior are provider-specific:
POST /v1/orders HTTP/1.1
Authorization: Bearer <server-side-token>
Idempotency-Key: order-op-7f2a9c
Content-Type: application/json

{
  "quote_id": "quote_4821",
  "currency": "USD",
  "items": [{"sku": "SKU-104", "quantity": 3}]
}
The expected result is one provider order associated with the internal operation, even if the same request is retried. Store credentials outside the example and never reuse the sample key in production. If the provider returns a conflict because the same key was used with different parameters, stop and investigate the request mismatch instead of generating another key automatically.
For a custom API you own, persist the idempotency key, caller scope, request fingerprint, processing state, and resulting response or resource ID. Enforce that the same key cannot be reused with materially different parameters. If a prior request is still executing, return a clear in-progress response or safely wait within a bounded interval. Test the race where two identical requests arrive at nearly the same time; a check-then-insert sequence without a database constraint can still create duplicate work.
Connect Systems With Webhooks and Async Jobs
Choose polling or webhook delivery intentionally
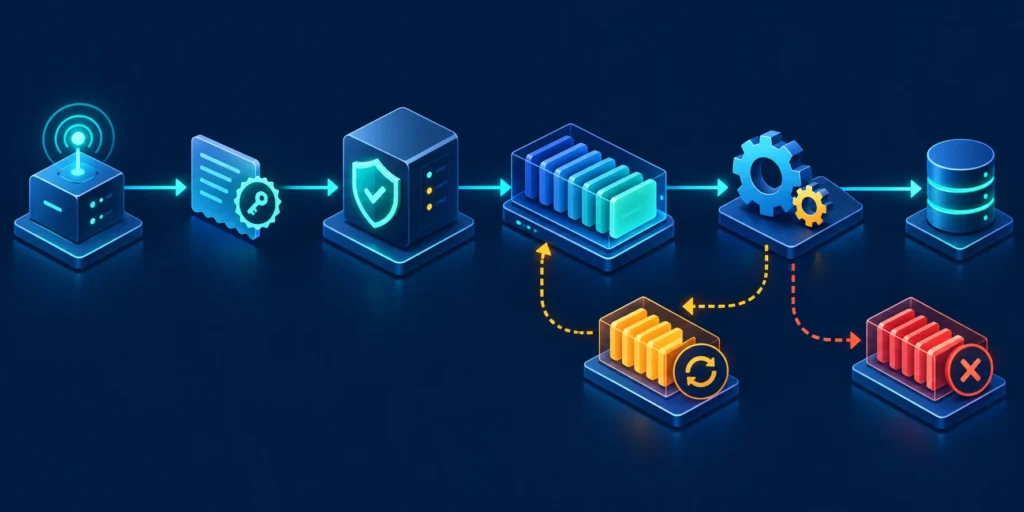
Polling is easy to explain but can waste requests and delay updates. A consumer asks for changes on a schedule, usually with a cursor or updated-since marker. Webhooks push a notification when an event occurs, reducing detection delay, but require a public endpoint, signature verification, duplicate handling, replay protection, and a recovery plan for delivery failures. Some systems use both: a webhook signals that something changed, and the consumer fetches the authoritative resource afterward.
Use polling when event delivery is unavailable, volume is small, or the consumer needs a periodic reconciliation. Use webhooks when near-real-time updates matter and the receiver can operate a secure endpoint. Do not treat a webhook payload as the only copy of a business record unless the provider guarantees that model. Store the event ID and enough status to detect duplicates, then fetch the current resource when the payload might be stale or incomplete.
Verify signatures before trusting events
For webhook providers that sign requests, verify the signature with the provider’s official SDK or documented algorithm before using the event. Preserve the raw request body if signature verification depends on exact bytes; parsing and re-serializing JSON first can change the signed representation. Keep the signing secret on the server, support rotation according to provider instructions, compare signatures safely, and reject invalid or stale requests.
A secure handler should do only the work needed to accept the event: validate the signature, identify the event, store it durably, and return the provider’s expected success response. Process business logic from a background worker. This prevents slow downstream calls from causing the provider to time out and resend the event. Stripe’s webhook documentation explains its HTTPS endpoint, signature-secret, testing, and delivery behavior; other providers differ, so follow the relevant provider’s current instructions.
Make event processing repeatable
Assume an event can be delivered more than once and that events may arrive out of order. Use the provider’s event ID as a deduplication key when available. Make the handler’s state transition safe to repeat: setting an invoice to paid based on a verified payment event is safer than incrementing a “paid count” each time the same event arrives. Check the event’s timestamp and current resource state when ordering matters.
For an asynchronous job, record a job ID, status, attempt count, creation time, last error class, and next action. Consumers should be able to check progress without polling excessively. Set a retention policy for completed jobs and protect the result if it includes customer data. Provide a way to cancel or retry where the operation permits it, and explain when a retry starts a new business operation instead of resuming the old one.
Decide who owns reconciliation
Webhooks can be delayed, rejected, or disabled. Build a periodic reconciliation path for high-value records such as payments, provisioning state, and fulfillment status. Compare a bounded time window using stable IDs and repair only differences the system can resolve safely. Send ambiguous cases to human review. An integration is not reliable merely because its happy path completes once; reliability includes the ability to find and recover from missed work.
Test the Contract and the Failure Paths
Cover unit, contract, and integration behavior
Unit tests should cover transformations, validation, authorization rules, and idempotency decisions without needing a live provider. Contract tests should verify that the request and response shapes match the agreed schema and that consumer assumptions remain valid. Integration tests should use a provider sandbox or a controlled test environment when available. Each layer catches a different class of error; a green unit test does not prove that credentials, network routing, or provider-side configuration are correct.
Keep representative request and response fixtures for ordinary, boundary, and rejected cases. Remove secrets and personal data before storing fixtures. Include a new enum value or unknown field when the provider permits it, so the client proves it can handle forward-compatible responses. If generated clients are used, generate them from the reviewed contract and keep the generation command reproducible.
Test failures deliberately
At a minimum, exercise: invalid input; expired or insufficient credentials; a provider timeout before and after a write; a rate limit; duplicate webhook delivery; a delayed event; a signature mismatch; a partial batch; an unexpected provider response; and a retry after the retry budget is exhausted. Verify the user-facing state, the logs available to operators, and the recovery path. A test that checks only an HTTP status code may miss a duplicate charge or a secret written to a log.
Use sandboxes for realistic provider behavior, but do not assume they perfectly match production. Keep a clear separation between test and live credentials, and ensure test events cannot trigger real fulfillment or customer notifications. Use synthetic accounts and data. Before production rollout, confirm which environment the endpoint and credential belong to, and make the intended environment visible in configuration and logs without printing the secret itself.
Exercise recovery and replay
Create a safe replay procedure before launch. An operator should be able to identify the failed item, understand whether the provider may already have completed the action, and retry without duplicating it. Test the replay procedure against a sandbox record. If replay requires editing a database row by hand, document the exact steps, required backup, and rollback, then prioritize replacing that operation with a controlled administrative tool.
For a migration or bulk synchronization, start with a small dry run. Compare source and destination counts, sample representative records, and record rejected rows. Provide a checkpoint so the job can resume after interruption. A “successful” run that skips failed records without reporting them is not successful; include totals for created, updated, unchanged, rejected, and retried records.
Operate, Monitor, and Evolve Integrations
Measure customer outcomes and system health
Monitor both technical behavior and the business workflow. Useful technical signals include request volume, latency percentiles, error class, provider rate-limit responses, retry count, queue depth, and oldest pending job. Workflow signals include orders synchronized, payments awaiting confirmation, records requiring manual matching, and time from event to completed action. An API with high availability can still be failing the business if important events are stuck in a queue.
Tag logs and traces with a non-sensitive correlation ID and integration name. Include tenant or account context only in a way that does not expose personal data or let one customer see another’s details. Define retention and access controls for operational data. Alert on thresholds that require action, such as a queue age exceeding the business deadline or a sudden rise in rejected credentials, rather than paging on every transient retry.
Roll out with a measured blast radius
Deploy a new integration behind a configuration flag or to a limited customer cohort when the architecture allows it. Start with a test account and a small set of records, then compare outcomes before expanding. Define in advance what would stop the rollout: duplicate side effects, an unexpected error rate, missing audit records, or a growing backlog. Name who can pause the flow and how the team will communicate the change.
For a workflow that can be disabled safely, document the effect of pausing it. Do pending events remain queued, expire, or require reconciliation? Will users see a warning? Can an operator restart processing after fixing credentials? A rollback should include data and queued work, not only the application binary. If a database migration is involved, use a compatible sequence that allows the old and new code to coexist during the transition.
Assign ownership and provider change management
Every production integration needs a product owner, technical owner, credential owner, support path, and escalation contact. Record the provider’s API version, the date the contract was reviewed, key dependencies, and the deprecation notice channel. Review vendor changes as part of normal maintenance; do not wait for a production outage to discover a removed field or a changed authentication flow.
Keep a short runbook next to the service dashboard. It should say how to confirm provider status, check credential scope and expiry, locate a failed request using its correlation ID, inspect queue age, pause processing, and replay one safe test item. Include the expected result after each step. If interface labels or dashboard paths vary by account or provider version, link to the current provider instructions rather than asserting a menu path you have not verified.
Close the loop with consumers
An API owner should announce material changes, document migration steps, and listen to consumer feedback. A contract is successful only when consumers can implement it and operate it predictably. Track questions that repeat in support and update examples, validation messages, and error docs. When consumers use the API in an unexpected way, determine whether the contract is unclear or the use is unsafe before simply adding a workaround.
For a practical view of how APIs fit into broader application architecture and launch planning, see our guide to <a href="https://fasenetwork.com/b2b-web-app-development-architecture-scalability-launch/">B2B web app development</a>.
Frequently Asked Questions
When should a company build a custom API?
Build one when a real consumer needs a stable, permissioned interface and the workflow cannot be met well by a supported provider integration, export, or message pattern. Name the consumer, owner, data, and operating commitment first. A custom API creates versioning, security, support, and uptime responsibilities; do not build one solely because another company has one.
Should we use REST or GraphQL for a business integration?
Choose the style that fits the consumer’s data needs, team expertise, caching model, and operational constraints. REST with clear resources is often straightforward for stable business workflows. GraphQL can help clients request related data flexibly but adds schema governance and query-cost considerations. The choice should follow actual consumers and requirements, not a blanket claim that one style is always superior.
How do we prevent duplicate orders after a timeout?
Create one idempotency key for the logical order attempt, persist its relationship to the internal order, and reuse it for retries of the same unchanged request. Confirm the provider’s key scope, parameter-matching behavior, and retention. If the provider does not support idempotency, use a stable external reference and a reconciliation check before retrying a write.
What is the difference between a webhook and polling?
Polling asks a provider for updates on a schedule; a webhook sends a notification when an event occurs. Polling is simpler but can be delayed and generate requests that return no changes. Webhooks can be faster but require a secure receiver, signature verification, duplicate handling, retry behavior, and reconciliation. Some systems combine both so webhook notifications trigger a fetch of the authoritative object.
Should a webhook handler do all processing before responding?
Usually not. Verify the request, store the event durably, and acknowledge it according to the provider’s contract; then process it asynchronously. Long-running downstream work increases timeout and redelivery risk. The worker must deduplicate events and expose failures in a queue or operational dashboard.
How should API versions be managed?
Prefer compatible additions and avoid removing or redefining fields that consumers already use. For a breaking change, publish a new major contract, provide migration examples, support a transition window when feasible, and observe which clients remain on the old version. Retire versions through a communicated schedule rather than silently changing their behavior.
What should we log for integration troubleshooting?
Log a correlation ID, integration name, operation, timing, outcome category, and retry number. Include only the minimum non-sensitive context needed to trace a record. Never log access tokens, signing secrets, full payment details, or raw payloads by default. Define who can access logs and how long they are retained.
How many retries should an integration use?
There is no universal number. Use bounded exponential backoff with jitter for failures that can recover, honor provider retry guidance, and define an overall deadline tied to the workflow. Do not retry permanent validation or authorization failures. Make one component responsible for retries so nested libraries and queues do not multiply attempts unexpectedly.
How do we test a third-party integration safely?
Use the provider’s sandbox and test credentials, synthetic data, and controlled endpoints. Test successful flows and failure paths such as expired credentials, rate limits, timeouts, duplicate webhooks, and partial batches. Verify that test activity cannot trigger live payments, fulfillment, or customer messages. Before launch, confirm that the production endpoint and credentials belong to the intended environment.
What should happen when a provider changes its API?
Track provider notices and API versions, review the change against your contract and consumers, and test it in a sandbox before rollout. If the change is breaking, implement a migration plan with an owner and date. If a provider gives limited notice, reduce the blast radius, prioritize the affected operation, and keep a reconciliation or manual fallback for critical customer workflows.
Conclusion
Reliable API development starts with a business outcome, turns that outcome into a clear contract, and carries failure handling through authentication, data mapping, retries, event delivery, testing, and operations. The most important design decisions are often the ones that prevent uncertain network behavior from becoming duplicate work or invisible data drift.
Before launch, walk one real workflow end to end. Confirm who owns each field, how the caller is authorized, what happens after a timeout, how duplicate events are handled, how an operator can find and safely replay failed work, and what evidence proves the integration succeeded. Roll out to a small cohort, measure both service health and customer outcomes, and expand only when the recovery path is understood.
Leave a Reply