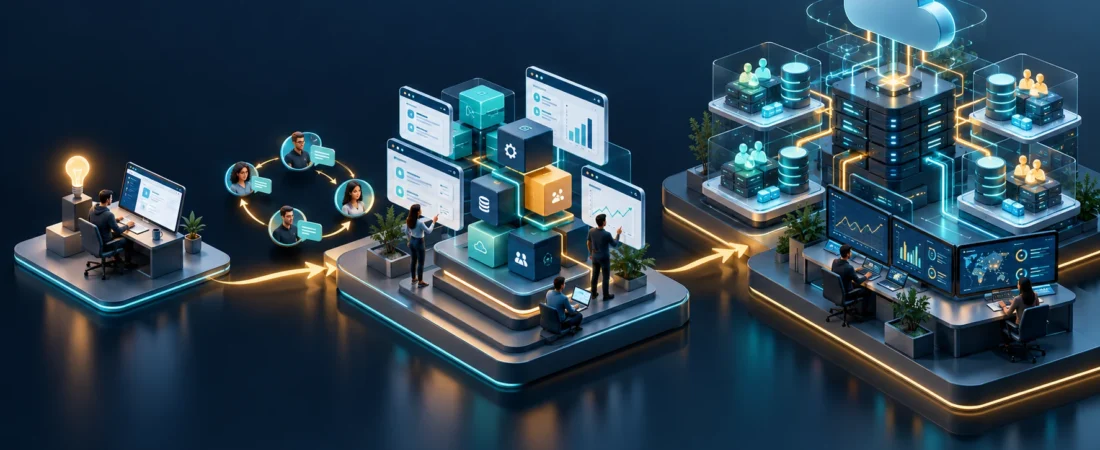
The SaaS product development lifecycle is not a one-time engineering project. It is a repeatable system for discovering a valuable problem, delivering a dependable product, learning from actual use, and operating the service as the customer base grows. A team can ship a polished first release and still have no viable business if buyers do not recognize the problem, adoption is too difficult, or the cost to serve each account grows faster than revenue.
This guide follows the decisions that connect product strategy to day-to-day engineering: customer discovery, minimum viable product scope, tenancy and security, delivery and reliability, pricing, and enterprise readiness. It is written for founders, product leaders, and technical decision-makers planning a B2B SaaS product or rebuilding an early product that has started to strain. The examples are hypothetical working examples, not claims about a real company or measured results.
Discover Customer Problem and Market Risk
Start with a workflow, not a feature list
Begin with a specific group of people and a recurring workflow they already perform. “Companies need better analytics” is too broad to guide product decisions. “A revenue operations manager reconciles campaign, CRM, and billing data every Monday before the forecast meeting” is more useful because it identifies a role, a trigger, a task, and a consequence. A clear problem statement helps the team decide whom to interview and what evidence to seek.
Write the problem in plain language before drawing screens. Capture who experiences it, when it occurs, what they do now, what the current workaround costs in time or risk, and who controls the budget. Keep the initial statement narrow enough that an interview can test it. If different customers describe different jobs, preserve those differences rather than blending them into a fictional average customer.
Interview for evidence instead of approval
People are usually generous when asked whether an idea sounds useful. That answer is weak evidence. Ask them to describe a recent instance of the problem, show the steps they followed, name the tools involved, and explain what happened when the process failed. Ask how frequently the work occurs, who else participates, and what an incomplete or delayed result means for the business.
For a practical discovery round, recruit a small set of people who match one customer profile, not a broad mix of unrelated roles. Conduct the interviews individually, use the same core questions, and take notes in a consistent format. Do not pitch the proposed product until after you understand the current workflow. A buyer who describes no recent example may still have an abstract interest, but that is different from demonstrated urgency.
Separate observations from conclusions
Record statements separately from interpretations. “We exported three spreadsheets last Friday” is an observation; “the customer needs a data warehouse” is an interpretation. Tag each observation by role, workflow step, frequency, consequence, workaround, and purchasing authority. After several conversations, look for repeated patterns and exceptions. A single passionate request should not silently become the roadmap for every customer.
Test willingness to change and pay
A painful problem does not automatically create a market. The buyer may lack budget, the work may happen too rarely, or a trusted incumbent may be good enough. Ask what the organization has already tried, what would need to change to adopt a new system, who approves the purchase, and what evidence a reviewer would require. These questions expose purchasing friction before the team builds a large product.
Use a lightweight offer to test commitment. For example, present a clearly scoped pilot with a defined outcome, duration, data requirements, security review, and price. The exact amount should come from the market and delivery economics; do not borrow a competitor’s price without understanding its packaging. A signed pilot, access to representative data, a scheduled implementation workshop, or an identified budget owner is stronger evidence than a positive survey response.
Turn discovery into a decision brief
Before planning the first release, write a short decision brief that summarizes the target account, user, job, current alternative, trigger, measurable outcome, buying process, and the most important unknowns. Include evidence that supports the opportunity and evidence that challenges it. State what must be true for the product to be worth building and what result would change the decision.
One useful format is a table with four columns: observation, evidence source, confidence, and product implication. A repeated manual reconciliation may support a workflow problem; an assumption that every customer uses the same CRM should remain marked as uncertain until tested. This separation prevents a plausible story from being mistaken for validated demand.
Set a clear next decision
Set a decision date for the next discovery checkpoint. The purpose is not to force a launch on a calendar, but to prevent indefinite research. At that checkpoint, choose one of three actions: proceed with a narrowly scoped test, revise the customer or problem definition, or stop investing in the opportunity. Document the rationale so a later team does not repeat the same interviews without learning from them.
Define MVP Scope and Validate Value
Define the smallest complete job
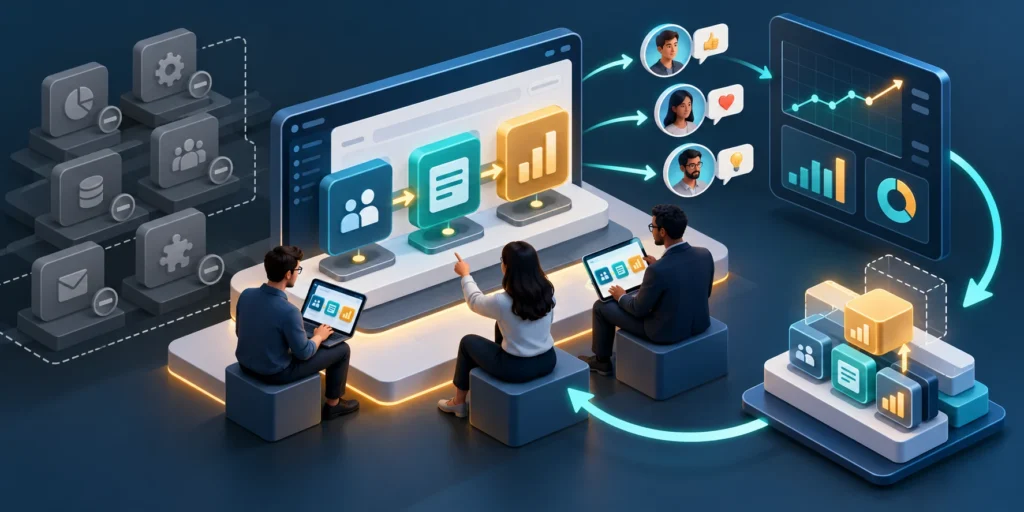
An MVP is not simply a product with fewer buttons. It is the smallest credible way to deliver and measure a meaningful customer outcome. Start with one job the target user must complete from beginning to end. If the product claims to shorten an approval workflow, the first version must let a user submit the relevant information, route it to the right reviewer, show its state, and preserve an audit trail if that trail is part of the buyer’s requirement.
Map the workflow from the user’s trigger through the moment they know the task is complete. Mark each step as essential, a manual service the team can temporarily provide, or explicitly out of scope. A manual step is acceptable during a pilot when it is transparent, controlled, and does not create an unsafe dependency. It is not acceptable to disguise a fragile manual operation as a feature that already scales.
Keep the first release focused
Choose one primary user and one buying context for the initial product. Enterprise products may have administrators, security reviewers, finance stakeholders, and end users, but the first release should still identify whose recurring work it improves. Add secondary personas only when they are necessary to complete the promised job or pass a real purchasing requirement.
Write testable acceptance criteria
Translate the job into observable acceptance criteria. “Easy to use” does not tell a developer or tester what to verify. “An administrator can invite a user, assign the correct role, and confirm that the user cannot view another tenant’s records” is testable. Keep each criterion connected to an outcome, a user role, and a condition that can be observed in the interface or in a controlled test.
For every workflow, document the normal path, a common failure, and the recovery path. If a data import fails halfway, the user should know what was imported, what was not, and whether retrying is safe. If an external API is temporarily unavailable, the system should show whether the request is queued, failed, or needs human action. These details often determine whether the product feels dependable even before it has many features.
Use a short release brief
Use a short release brief to keep scope visible:
- Target user and job: who is completing what task, and why now.
- Outcome: what observable change indicates the job is complete.
- In scope: the minimum workflow and controls required to achieve it.
- Out of scope: attractive requests that do not prove this release’s assumption.
- Risks: data, security, integration, operational, or commercial uncertainties.
- Learning plan: the events, interviews, and customer review that will inform the next decision.
The brief should be short enough to read in a planning meeting. It is not a substitute for detailed technical design where the product handles sensitive data, payments, or regulated workflows. It gives product, design, engineering, and sales a shared boundary for the first release.
Separate product learning from delivery activity
Counted output such as tickets closed, screens built, and code merged shows activity, not whether a customer has received value. Before development begins, choose a small number of measures that connect to the job: successful task completion, time to first completed outcome, percentage of imports requiring manual repair, or repeat use by the intended role. Define how each measure is calculated and what event produces it.
Avoid selecting a single vanity metric such as total sign-ups when the product requires an administrator to configure data before a user can succeed. A better activation measure may require a new account to complete its first real workflow, invite a teammate, or receive a useful result. The measure should reflect value actually delivered, not a click that is easy to increase without improving the product.
Compare the pilot with a baseline
For a pilot, set a baseline before introducing the product. If the current process takes a customer’s team several handoffs, record how those handoffs work and how long each typically takes. After launch, compare the same workflow and note changes in volume, customer mix, and process conditions. Label an observation as directional when the pilot is too small to support a general conclusion.
Keep validation honest
A small sample can reveal usability defects and workflow mismatches, but it cannot prove broad market demand on its own. Treat pilot findings as evidence about the participating accounts and the conditions you observed. Avoid turning a single successful deployment into a universal claim about time saved, conversion lift, or cost reduction.
When the pilot does not achieve the expected outcome, investigate the whole path before adding features. The issue may be data quality, an unclear setup step, poor access to a system owner, a process that varies by account, or a product behavior that fails under normal use. A short problem review should describe what happened, who was affected, how it was detected, what the team changed, and how the next test will show whether the change helped.
Choose SaaS Architecture and Tenant Model
Decide how tenants share and isolate resources
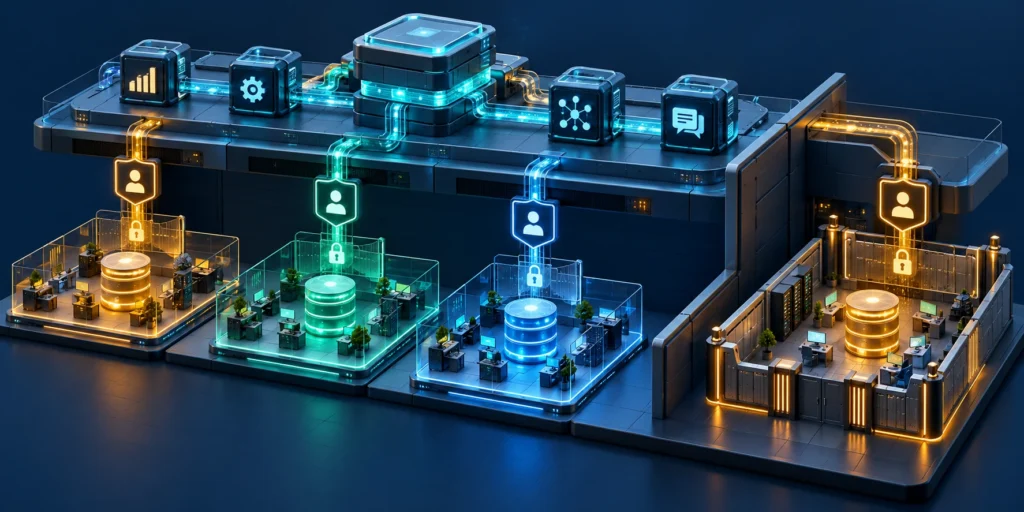
A tenant is the customer organization or logical customer environment that the service must manage. The tenancy model affects more than database layout: it shapes onboarding, identity, support, deployments, monitoring, cost allocation, and the ability to isolate one customer’s data from another’s. AWS describes pool, silo, and bridge approaches as patterns with different operational and isolation tradeoffs; no one model is right for every SaaS product.
In a pooled model, many tenants share application and infrastructure resources. It can simplify operations and improve resource utilization, but it raises the importance of authorization checks, tenant-aware observability, and controls that prevent cross-tenant access. A silo model assigns dedicated resources to a tenant or group; it can support stronger isolation or special requirements, but increases provisioning, patching, and support work. A bridge model combines shared and dedicated layers to balance those needs.
Match isolation to customer and risk needs
Choose based on customer requirements, threat model, data sensitivity, regulatory obligations, workload variability, support capability, and unit economics. A large enterprise may request a dedicated database, but the request does not automatically justify a separate deployment if the actual requirement can be met by a tested isolation boundary. Conversely, shared infrastructure should not be chosen purely because it appears cheaper if the team cannot demonstrate safe tenant separation.
Keep operations unified
Make onboarding and operations part of the design for every model. If some accounts use shared services and others use dedicated resources, the provider still needs one reliable way to provision, configure, update, monitor, and support them. A collection of individually managed customer installations can become a costly custom-services business rather than a product with repeatable operations.
Enforce tenant boundaries at every request
Never trust a tenant identifier supplied by a browser as proof of authorization. Derive the user’s allowed tenant context from the authenticated identity and verify that context on every operation that reads or changes tenant-owned data. Apply the same discipline to background jobs, exports, webhooks, administrative tools, search indexes, and file storage; a secure page can still leak data through a report or asynchronous task.
For an adjacent implementation view of architecture, scalability, and launch sequencing, see our practical guide to B2B web app development.
Use tenant-scoped queries
For a relational data model, a tenant key may appear in business tables and be part of the access path. A simplified conceptual query can make the intended boundary visible:
SELECT id, status, created_at
FROM orders
WHERE tenant_id = :authorized_tenant_id
  AND id = :requested_order_id;
Here, :authorized_tenant_id must come from the authenticated server-side authorization context, not directly from an untrusted request parameter. The example is not a complete access-control implementation. Teams should review how the chosen framework, database, and query layer enforce the boundary and test both allowed and denied access paths.
Test both allowed and denied access
Build negative tests deliberately. Create two test tenants with distinct records, then attempt to fetch, update, export, or delete tenant A’s record while authenticated as tenant B. Verify that every route denies access and does not reveal whether the other customer’s record exists. Include identifiers in nested resources and background jobs; a correct check on the first page does not guarantee that a later export uses the same tenant context.
Keep privileged support access separate from routine user access. If staff need customer-context access to diagnose an issue, require a legitimate support reason, record who accessed which tenant, and define how the access ends. A hidden administrator bypass is difficult to audit and can turn a support feature into a cross-tenant data path.
Design identity, permissions, and enterprise access
Model the relationship between a person, a tenant, and a role explicitly. A person may belong to more than one customer organization, and the same role name can have different permissions in different tenants. Make it clear in the interface which organization is active before a user performs a sensitive action. Enforce permissions on the server even when the interface hides unavailable controls.
For B2B buyers, consider the access requirements that can affect adoption: single sign-on, identity-provider initiated login, user provisioning and deprovisioning, multi-factor authentication, role assignment, session controls, and audit events. Do not claim a standard or certification merely because a product includes one related setting. Identify the customer requirement, the implementation boundary, and what evidence a security reviewer can actually inspect.
Make the permission model reviewable
Prepare a permissions matrix before building many roles. List actions such as invite, export, manage billing, change integration credentials, view audit history, and delete data. Map each action to roles and tenant context. This exercise often reveals that an early product needs a small set of understandable roles rather than dozens of inconsistent permissions.
Plan data lifecycle and portability
Decide what the service stores, why it stores it, how long it remains, and how a customer can retrieve or delete it. Define retention for account data, activity logs, backups, and derived analytics separately. Deleting a customer record from the main table may not remove copies in a backup or an event stream, so describe and implement those boundaries accurately.
Make import and export part of the product plan when customers need to migrate from existing tools or exit the service. A useful export should be documented, contain the customer’s own data in a usable format, and handle large files safely. A migration plan should identify mapping errors, duplicate records, rejected rows, and the person who can resolve them. Data portability reduces onboarding friction and helps the company answer procurement questions.
Migrate without breaking existing tenants
For a schema change, specify how existing customer data will be handled and what happens if a deployment stops halfway. Prefer changes that can be rolled out in compatible stages: introduce a new field, support both shapes during transition, backfill safely, and remove the old path only after verifying usage. Always test migration and recovery against representative data rather than assuming a successful development migration proves production safety.
Choose a service shape you can operate
Microservices are not a maturity badge. They add service boundaries, network failure modes, deployment coordination, observability needs, and ownership overhead. A well-structured application with clear modules may be a better starting point for a small team. Split a service when a real boundary improves independent scaling, fault isolation, security, deployment, or ownership enough to justify the added operational cost.
Start by mapping the product’s critical workflows and dependencies. For each external service, record its owner, credentials, expected latency or availability, retry behavior, and what the user sees during an outage. Avoid retries that can duplicate a charge or create multiple records; use idempotency keys or another provider-supported deduplication approach when the operation must be safe to retry.
Choose managed services deliberately
Select managed infrastructure when it reduces undifferentiated maintenance and fits your control requirements. A managed service still needs configuration, access control, cost monitoring, backup, and failure planning. The decision is not “cloud versus no cloud”; it is whether the team understands the service boundary and can operate it without making customer promises the platform cannot meet.
Build Reliable SaaS Product and Delivery System
Make security and quality part of the workflow
Security is not a final review reserved for launch week. Identify the data assets, trust boundaries, identities, and misuse cases while the workflow is being designed. Translate the risks into controls and tests: authorization checks, input validation, secret handling, dependency updates, audit logging, rate limits, and safe error behavior. The NIST Secure Software Development Framework provides a set of practices that can be integrated into an organization’s existing software development lifecycle; it is guidance for organizing work, not a certification by itself.
Use a threat review proportionate to the product. For a service that imports customer contacts, ask how malicious files, malformed encodings, overly broad API credentials, or unauthorized exports could affect the tenant. For a workflow that changes billing, identify who can initiate the change, how it is confirmed, how it is logged, and how accidental duplicates are prevented. A short, concrete threat review is more actionable than a generic checklist copied into every ticket.
Protect credentials and customer data
Keep secrets out of source code and logs. Use the secret storage mechanism supported by your deployment platform, grant each workload only the credentials it needs, and rotate credentials when staff or vendors lose access. Do not use production customer data in development unless the organization has a documented and approved method for protecting it. For debugging, prefer synthetic or appropriately minimized data.
Automate the release path without removing judgment
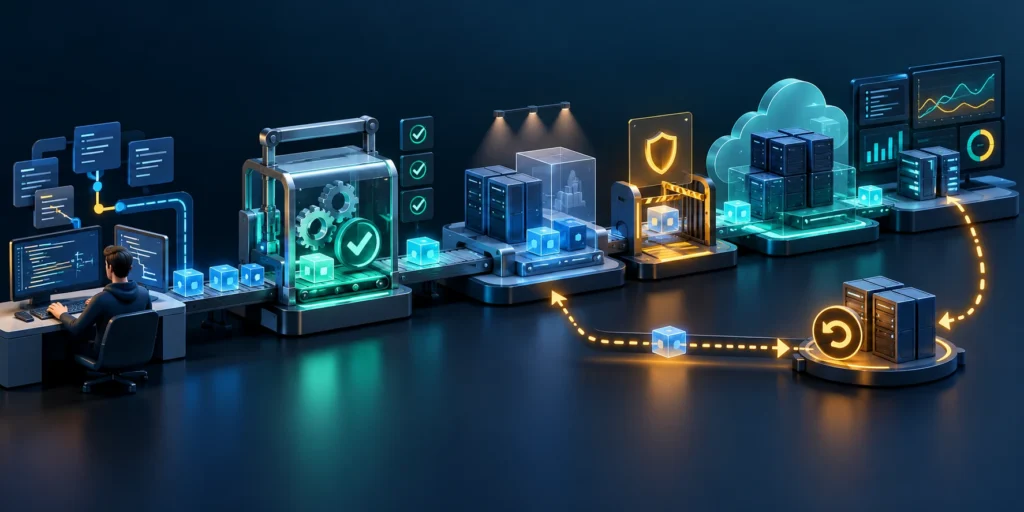
A release pipeline should make routine changes repeatable: format and static checks, automated unit and integration tests, security checks appropriate to the stack, a deployable artifact, and a controlled rollout. The exact checks depend on the product, but failures should be visible and owned. A green pipeline is evidence that selected checks passed; it does not prove that every customer workflow is correct.
Use a staging environment to test release behavior with representative configuration and synthetic data. Validate migrations, authentication callbacks, tenant routing, billing events, background jobs, and rollback steps where relevant. Staging should resemble production in the ways that matter, while avoiding uncontrolled copies of customer information.
Control rollout and rollback
Roll out changes in a way that limits the size of a failure. A small customer cohort, internal users, or a feature flag can help the team observe behavior before broad release. Define the signal that would pause or reverse the rollout, the person authorized to act, and the rollback or mitigation path. A rollback plan that has never been tested is only a hypothesis.
Define reliability around customer workflows
An uptime percentage alone can hide whether users can complete the job they bought the product for. Define a few service indicators tied to the critical path: successful sign-in, successful completion of the core workflow, time to process an import, or time to receive an integration result. For each indicator, decide what counts as success, where the measurement comes from, and how it will be reviewed.
Set service objectives only after understanding customer needs and system behavior. A target that the team cannot measure or influence will not help operations. A target that is too strict can create expensive work without improving the customer’s actual experience. If the service supports an asynchronous workflow, explain queue delay and recovery behavior rather than promising that every operation is instantaneous.
Make telemetry tenant-aware
Instrument logs, metrics, and traces with enough context to diagnose issues, while avoiding secrets and unnecessary personal data. Include a tenant-safe identifier when it helps locate an affected account, and restrict who can access detailed customer context. Monitor aggregate health as well as differences in usage and failure rates across tenant tiers; averages can conceal that one customer is experiencing a severe issue.
Practice incidents and recovery
Write a concise incident runbook for the failures most likely to interrupt the product: identity provider outage, database or storage unavailability, failed migration, compromised credential, broken payment callback, or a bad release. The runbook should state how to detect the issue, who owns response, what to communicate, how to mitigate safely, and where the evidence is recorded. Keep it near the system operators actually use.
Backups matter only when recovery is possible. Define what is backed up, where the copies are stored, who can access them, and how often restoration is practiced. A restore exercise should verify data consistency and customer-facing behavior, not just that a file can be downloaded. Record the observed recovery time and the data interval that could be lost, then compare both with the business requirement.
Turn incidents into system learning
After a meaningful incident, focus the review on system learning rather than blame. Capture the timeline, customer impact, detection gap, contributing conditions, response decisions, and specific follow-up work with owners. If the same class of incident recurs, revisit whether the earlier corrective action changed the underlying failure path.
Pricing Economics and Enterprise Readiness
Connect pricing to customer value and service cost
Pricing affects product design and operating economics. A useful model connects what the customer values to a unit the company can explain and measure: seats, active workflows, transactions, data volume, or a tier with clear capability boundaries. The unit should be understandable before purchase and predictable enough that an expanding customer does not feel punished for receiving value.
Estimate the cost to serve an account across infrastructure, third-party API usage, support time, onboarding, storage, and operational review. Track both average consumption and unusual spikes. A low subscription price can become unsustainable when a small number of accounts generate heavy processing or require repeated manual intervention. A high price can be hard to justify when the product does not deliver a clear result.
Model economics with explicit assumptions
Use a sample model to expose assumptions rather than present a forecast as fact. For example, if a hypothetical account pays a monthly fee, list its expected infrastructure use, support hours, onboarding effort, payment costs, and gross margin assumption. Change one assumption at a time and observe the impact. Label the numbers as estimates until real usage and renewal data replace them.
Design packaging without artificial feature walls
Packages can help customers choose the appropriate level of service, but arbitrary limits create confusion. Tie tiers to real differences in value, service requirements, or cost: more advanced workflow controls, administrative capability, audit retention, support response, or a scale threshold. Explain exactly which capabilities are included and how a customer moves to another tier.
Test packaging in sales conversations and onboarding. Ask buyers what they need to complete procurement, what they expect to be included, and which restriction would block adoption. If a customer cannot tell whether a necessary integration is part of the plan, simplify the presentation. The aim is not to hide the price until a sales call; it is to make the value and boundaries clear enough for a qualified buyer to decide.
Make usage charges predictable
Usage-based pricing needs operational safeguards. Define the billable event, rounding rules, free allowance, alerts, and what happens at a limit. Provide customers with a way to understand their current consumption and likely bill. If a background retry can increase a usage count, prevent double counting or disclose the behavior before it creates an unexpected charge.
Scale using observed bottlenecks
Growth does not automatically require a rewrite. Measure the service under representative workloads and identify the limiting resource: database queries, external API limits, synchronous processing, memory, storage, or operational handoffs. Establish a baseline and reproduce the bottleneck before changing architecture. Prematurely splitting services can create more failure modes without addressing the actual constraint.
For a batch import that slows down as customer data grows, inspect query plans and batch size, measure memory and queue delay, and test with datasets that resemble the largest expected account. For an external API bottleneck, confirm the provider’s current limits, apply backoff where appropriate, and communicate when work is delayed. For an operational bottleneck, automate repeated onboarding or support steps only after the team understands the variations that must remain safe.
Track consumption by tenant
Use tenant-aware metrics to understand whether one account is consuming a disproportionate share of a shared resource. This can inform fair-use controls, customer conversations, infrastructure allocation, or a dedicated deployment option. Make any rate or usage limit visible and connected to product terms; silently throttling a paying customer can turn a scaling issue into a trust problem.
Prepare enterprise readiness as product work
Enterprise readiness is not one feature or a logo on a sales slide. Buyers may ask about identity, roles, auditability, availability, data handling, incident communication, vendor dependencies, procurement evidence, and support ownership. The exact requirements vary by industry and customer. Build an evidence inventory that distinguishes controls already implemented, controls planned, and items that depend on a hosting provider or another vendor.
Create a concise security and operations packet with accurate answers: data categories processed, retention and deletion boundaries, access-control approach, encryption scope, backup and recovery practices, incident contact, subprocessor list where applicable, and the current status of any attestations. Do not claim a certification, compliance status, or data residency guarantee unless the organization has evidence and authority to make that claim.
Make implementation repeatable
Document required customer inputs, identity setup, data mapping, validation steps, ownership, and the rollback or pause plan. A customer should know who is responsible for each step and what result confirms completion. If onboarding repeatedly depends on an engineer copying production data by hand, treat that as a product and risk gap rather than an invisible service habit.
Use a staged launch and learning loop
A launch plan should combine product readiness, customer support, technical operations, and commercial communication. Before a wider release, confirm that the critical workflow works with representative data, the support team can diagnose common failures, the monitoring signals are visible, and customers know how to get help. A launch checklist should be tailored to the product rather than copied as a generic ceremony.
Start with a cohort whose needs and operational conditions the team understands. Review support requests, task completion, error patterns, onboarding friction, cost to serve, and renewal signals. Separate issues that block safe use from requests that can wait. When several customers ask for the same feature, investigate whether it represents a shared job, a missing configuration, or one account’s specific process.
Close the learning loop
Turn the findings into a decision for the next cycle. Continue investing, narrow the product, adjust packaging, improve onboarding, or stop a feature that does not earn its operational cost. A product lifecycle is a series of evidence-based decisions, not a commitment to keep adding scope because a roadmap exists.
Frequently Asked Questions
What should a SaaS MVP include?
An MVP should include the smallest complete workflow that can deliver and measure a valuable outcome for a defined user. It also needs the security, reliability, and support controls required for that workflow to be used safely. Features that do not test the primary assumption can wait, while essential recovery or access controls should not be cut merely to reduce scope.
How long should SaaS product development take?
There is no reliable universal duration. Timing depends on workflow complexity, integrations, security review, customer access, data migration, team capacity, and whether a pilot is being used to learn. Break the work into a discovery checkpoint, a deployable first workflow, and measured customer validation instead of promising a date before dependencies are understood.
Should an early SaaS product use microservices?
Not by default. A modular application can be easier for a small team to develop and operate. Split services when independent scaling, deployment, fault isolation, security boundaries, or team ownership justify the extra network and operational complexity. Base the decision on observed constraints and responsibilities, not on the label associated with a modern architecture.
Is a shared database safe for multiple tenants?
It can be appropriate when the product consistently enforces tenant authorization and tests isolation across every access path. The team must account for queries, exports, background jobs, search, files, administrative support, and logs. If the organization cannot demonstrate those controls or meet a customer’s isolation requirement, consider a more isolated model for the relevant data or service.
When should a company offer a dedicated tenant environment?
Offer dedicated resources when a real requirement—such as isolation, regulatory constraints, workload interference, or a negotiated service boundary—justifies the cost and operational work. Define what “dedicated” means across application, database, networking, backups, and support. Keep provisioning and updates repeatable so dedicated accounts do not become manually maintained forks.
How should a SaaS team choose its pricing metric?
Choose a metric customers can understand that tracks value or a meaningful cost driver. Test it in buyer conversations, estimate the cost to serve, and model normal as well as peak use. Explain allowances, overages, and limits before they affect a bill. Replace assumptions with observed usage and renewal evidence as the product matures.
Which metrics matter after launch?
Start with measures tied to the product’s core job: successful completion, time to first value, repeat use by the intended role, reliability of the critical workflow, support burden, and cost to serve. Define event rules carefully and segment by relevant account type. A large sign-up total is not useful if the intended customers cannot complete the job.
How can a SaaS team scale without a complete rewrite?
Measure representative workload, locate the actual bottleneck, and make a targeted change. Examine database behavior, queue delay, external-provider limits, memory, and operational work before changing service boundaries. Test the change under a realistic load and track whether it improves customer-facing results without weakening isolation or reliability.
What should happen when a SaaS release causes an incident?
Protect customers first: identify affected workflows, stop or reverse the change when appropriate, and communicate accurate status through the agreed channel. Preserve evidence, restore service safely, and record the timeline. Then review the detection and response gaps, assign corrective work, and verify that the failure path has changed rather than treating the incident as an isolated mistake.
What does enterprise readiness mean for a SaaS product?
It means the product and provider can answer the customer’s actual requirements for access, data handling, auditability, reliability, support, and procurement with accurate evidence. It does not mean every product needs every control or certification. Identify which requirements apply to the target market and distinguish implemented safeguards from planned work or vendor-dependent commitments.
Conclusion
A durable SaaS product grows through a connected sequence: understand a real customer workflow, prove a valuable outcome with a focused release, choose tenancy and security boundaries that fit the business, build a release and recovery system the team can operate, and scale against observed demand. Each stage should produce evidence for the next decision rather than merely a larger backlog.
Start with one customer profile and one complete job. Write down what must be true, test it with real users, and keep assumptions visible. As adoption grows, invest in tenant-aware operations, clear permissions, predictable pricing, and an enterprise evidence package that reflects what the service actually does. That discipline lets the product expand without confusing growth with success.
Leave a Reply